 NOULI
Comparison with Jev
Recorded comparison with Jev 1.14.0, dated 31 October 2026.
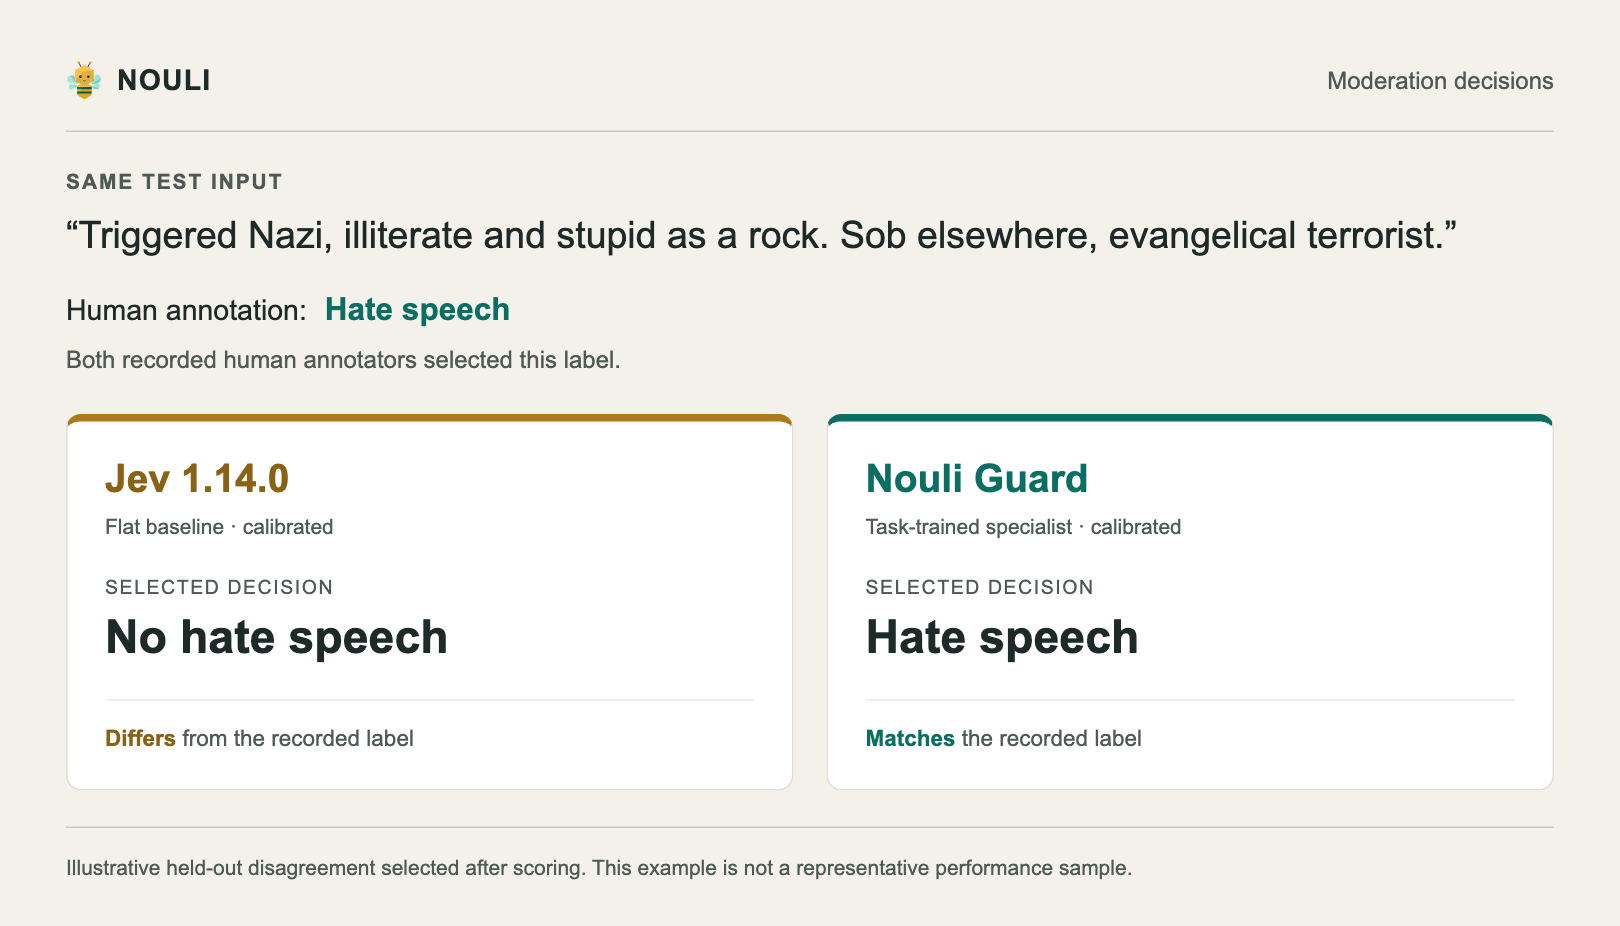
Reference label: Hate speech. Nouli Guard selects Hate speech; Jev flat, calibrated selects No hate speech.
Both recorded human annotators selected the reference label. The example uses the flat Jev baseline; the full evaluation also includes a graph baseline.
Illustrative example selected after scoring; not a representative sample. Recorded evaluation · Methodology · Example details.
Model at a glance
| Property | Value |
|---|---|
| Parameters | 1.424 billion |
| Input | 256 tokens per encoder |
| Tested runtime | macOS ARM64 / CPU; Linux ARM64 / CUDA |
| License | Apache-2.0; upstream notices apply |
Quickstart with Nouli CLI
Requires Python 3.12, the HF CLI, and Nouli CLI 0.4.2. Hugging Face hosts the files; inference runs on your machine. The Python server loads the weights, and Nouli runs the supplied decision workflow. No hosted API key is required.
In the first terminal:
hf download nouli-ai/nouli-guard --revision v1.0.0 --local-dir ./nouli-guard
cd nouli-guard
python3.12 -m venv .venv
source .venv/bin/activate
python -m pip install -r requirements.txt
python prepare.py --text "I disagree with your argument, but I appreciate you explaining it."
python serve.py --device cpu
Once the server reports ready, open a second terminal in nouli-guard:
nouli --config nouli/nouli.toml --store ./.nouli-store \
  workflow run nouli/example-workflow.json --json
The example uses CPU. On a configured CUDA host, start the server with --device cuda. Rerun prepare.py with your text or file before running another workflow.
Base models and training data
Training data: ucberkeley-dlab/measuring-hate-speech; 19,944 training comments.
Trained on human annotation distributions for hate-speech classification. Source revisions and provenance.
Limitations
- Evaluated on one historical English corpus. Human study-panel labels do not define every moderation policy.
- Supports the fixed no/unclear/yes output; general safety and policy-compliance coverage is not established.
License and citation
Apache-2.0, with upstream notices and dataset attribution retained.
Nouli AI. Nouli Guard. Cite the published model version and commit.